The 153-item index is a map, not a software package
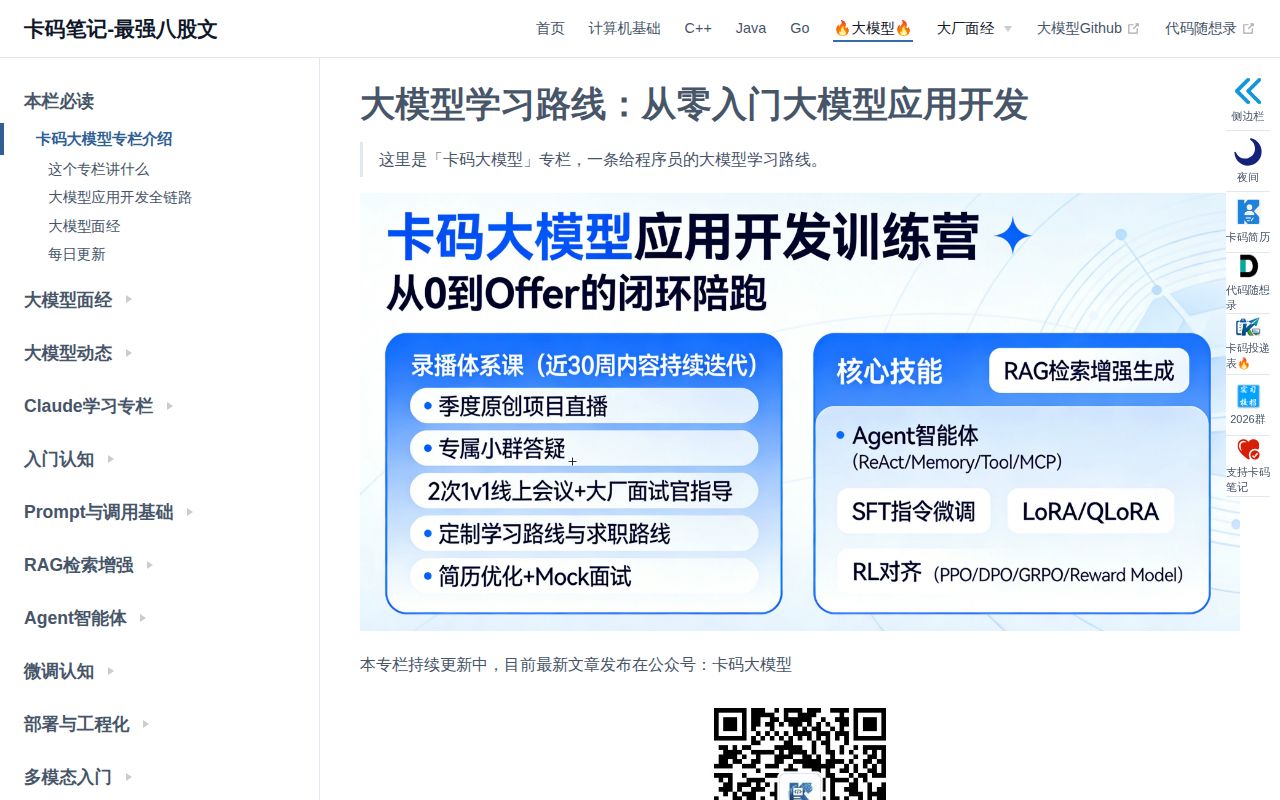
LLM-Master organizes Chinese articles for programmers who want to move into LLM application development. The route begins with model calls, then moves through RAG, agents, production engineering, Transformer mechanics, and interview preparation. Its index counted 153 tutorials and interview resources when checked. GitHub reported no primary programming language because the repository is mostly written material.
The strongest feature is sequencing. Stage 1 asks you to build streaming output, structured responses, error handling, and cost accounting. Stage 2 adds a knowledge base with hybrid retrieval, citations, an offline evaluation set, and error analysis. Later stages require an interruptible agent and a capacity report containing latency and throughput measures. Those completion criteria are more useful than a folder of unrelated links.
The curriculum is entirely aimed at Chinese readers. The README identifies the language as Chinese, the article titles and explanations are Chinese, and no English track is listed. Issue 1 points to a separate Ukrainian translation of 123 articles, but that fork also removed China-specific job and account material and added localized content. It is not an English mirror of the current 153-item index.
What happened when we ran it
The lab record has no executable result for commit 5991623. GitHub supplied no primary language, there was no supported ecosystem to install, and the repository had no Dockerfile. That means there is no measured install time, package count, build result, test result, disk total, or dependency audit for us to turn into a software-quality claim.
This is a documentation collection, so the missing runtime is understandable. It still changes how the repository should be judged. A roadmap can tell you to create a RAG evaluation set, but it does not provide one measured application whose retrieval metrics we can reproduce. A deployment article can name TTFT, TPOT, P99, and goodput without proving a particular server reaches any target.
Across 153 tutorials and interview resources, learners must supply their own environment, model access, data, and tests. The repository should be read as instruction and synthesis. If you need a course where every lesson ends in an executable notebook with pinned dependencies, mlabonne/llm-course is closer to that format.
Six stages keep beginners from starting with agents
The main learning path uses 6 stages, beginning at stage 0 with role and system awareness. Model calls come before retrieval. Retrieval comes before agents. Production concerns follow the agent stage, and Transformer internals arrive near the end. That order resists the common mistake of building an autonomous workflow before learning structured output, failure handling, cost, and evaluation.
Topic pages let experienced developers skip the linear route. The RAG section covers chunking, embeddings, vector databases, hybrid retrieval, reranking, citations, and evaluation. Agent material includes tool contracts, state, memory, planning, permissions, recovery, and multi-agent communication. Deployment articles move into KV cache, quantization, load testing, capacity, and serving projects such as vLLM and SGLang.
Breadth has a cost. A reader can move from attention math to Claude Code account restrictions, then to Chinese hiring interviews and current model pricing. Those are different kinds of evidence with different shelf lives. Use the roadmap for order, then choose one topic page and build the project it describes rather than trying to read all 153 entries as a textbook.
Four projects turn reading into checkable work
The README proposes 4 portfolio projects: an AI business assistant, an enterprise knowledge base, a tool-using agent, and a production AI service. Each has a minimum delivery standard. The assistant needs exception handling, token accounting, and automated tests. The knowledge base needs a fixed evaluation set and classified failure cases. The agent needs traces, recovery, a budget ceiling, and completion-rate evaluation.
These standards are the repository's most quotable advice because they demand evidence rather than a demo screenshot. The production-service project asks for P99, time to first token, time per output token, goodput, and a capacity report. None of those numbers are supplied by the course, which is appropriate: they should come from the learner's workload and hardware.
The projects are descriptions rather than starter kits. There is no course container, package manifest, test runner, or hosted grading system in the repository. You decide the language, providers, frameworks, and data. That freedom suits an experienced programmer changing specialties. A true beginner may prefer a notebook course before returning to these broader delivery standards.
Two open corrections show why the math needs checking
Open issue 2 identifies two specific numerical errors. One article's cascade-routing example says a 10-times-cheaper small model produces costs of 10 plus 10 plus 30; the reporter recalculates the example as 7 plus 33. Another sentence says attention at a 200K context requires 4 billion pairwise operations, while 200,000 squared is 40 billion.
LLM-Master had 4 issues open when checked, including the two arithmetic reports. Those reports do not invalidate 153 articles. They do show that polished explanatory prose can carry arithmetic mistakes. Before using a figure in an architecture decision or interview, recompute it and check whether an issue or later edit addresses the discrepancy. The same rule applies more strongly to pricing and model-access articles, whose facts can change without a repository error.
A September push signals activity, while releases are absent
GitHub showed 1,073 stars, 4 combined issues and pull requests, an MIT license, and a September 19, 2026 push. There was no latest GitHub release. The repository's value therefore comes from the current main branch and external Kamacoder notes site, not a versioned curriculum snapshot. Pin a commit if a team plans to teach from it.
For a Chinese-reading application developer, LLM-Master gives a sensible order and unusually concrete project acceptance criteria. It is less convincing as a sole technical reference because topics move quickly and the open arithmetic corrections are easy to verify. Read it to choose the next skill, build something measurable, and use primary documentation for the facts your system depends on.