When Crawlee earns its place
Crawlee is worth evaluating when a collection job needs to keep unfinished URLs and save results between runs. Its README documents a persistent URL queue, pluggable storage and configurable retries. Those features give a recurring crawler a common structure around the extraction code.
The README describes HTTP and browser crawling through one interface. Its browser example puts extraction logic in a request handler. The adoption question is whether your job needs that surrounding crawl management. A short browser script may need less machinery.
What happened when we ran it
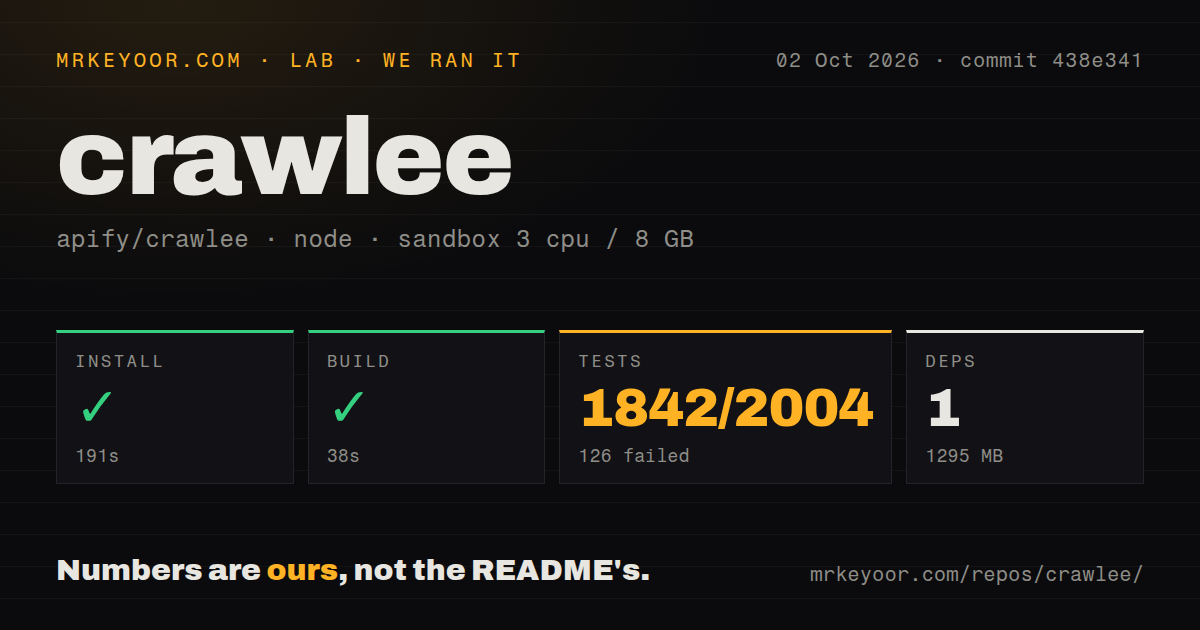
Crawlee built in 38 seconds in our sandbox, but 126 tests failed.
This was the recorded October 2, 2026 run at commit 438e341, not a new test. Installation succeeded in 191 seconds. The test command exited with code 1 after 623 seconds, with Vitest reporting 1,842 passed, 126 failed and 36 skipped out of 2,004 tests. Many tests executed, but these summary counts do not establish code coverage or exhaustive unique coverage.
The supplied tail names failures in Puppeteer crawler and launcher cases, Playwright launcher cases, browser-pool behavior and memory information. It does not show the underlying exceptions. Those filenames identify places to investigate; they do not establish whether missing browser binaries, sandbox restrictions or Crawlee defects caused the failures.
The configured sandbox had 3 CPUs, 8 GB RAM and image label lab-node:22. The exact runtime version is not established by that label. The installation record reports 1 dependency and 1,295 MB on disk. The dependency entry is not a verified inventory of transitive packages or a basis for estimating a consumer project's installation cost.
The checkout scan recorded monorepo workspaces, a tests directory and 9 CI workflow files. It detected no Dockerfile. The current README advertises deployment Dockerfiles, so inspect the deployment path you intend to use rather than treating the checkout scan as a finding about every documented option.
Our run did not measure crawl throughput, extracted-data quality or success against protected sites. A successful build also does not establish that a browser can launch on your intended host.
Local storage and browser setup
The README's example uses PlaywrightCrawler, reads a page title, saves it through Dataset.pushData and adds discovered links with enqueueLinks. It documents ./storage under the working directory as the default storage location. The README also says Crawlee runs outside Apify's platform; it does not present an Apify account as a prerequisite for this local workflow.
This describes the supplied example. Our repository run did not separately execute or validate it.
The manual installation adds both Crawlee and Playwright because Playwright is not bundled with Crawlee. Check the selected browser's deployment requirements and exercise browser startup on the intended host.
For a recurring job, define which URLs belong in the crawl before enabling link discovery. Start with a bounded set, inspect saved records and review failed requests. These are proposed validation steps, not checks completed in our recorded run.
Proxy rotation and session management are documented features. They do not demonstrate that Crawlee supplies a proxy service or that a target will accept your traffic. The README's bot-protection claims remain upstream claims that our run did not verify.
Check the requirements for your selected version
The current README specifies Node.js 22.13 or higher. The supplied primary extracts do not establish the version-specific requirements of measured commit 438e341, and the sandbox image label does not establish its exact runtime. Check the requirements attached to the version you install.
Crawlee documents HTTP crawling with HTML parsers and browser crawling with Playwright or Puppeteer. If the required information is present in the HTTP response, evaluate the HTTP path first. If extraction requires JavaScript rendering, evaluate the browser path. We have not measured a performance difference between those choices.
Activity does not resolve the test result
The supplied repository metadata records a last push on October 31, 2026. The issue listing includes an October 30 report about multiple-cookie response handling in AdaptivePlaywrightCrawler with Firefox. The supplied issue listing does not establish its resolution. It also does not establish whether your selected release is affected.
The supplied latest-release record identifies v3.18.2, dated September 29, 2026. Its notes describe fixes for a browser-pool page close that never settles and a timed-out task's context leaking into the pool loop. These notes document upstream changes; they do not establish the cause or resolution of our recorded failures. The measured checkout remains commit 438e341, not a verified test of release v3.18.2.
Alternatives depend on the job
Playwright is a framework for web automation and testing. Its README documents a library for browser automation scripts. Evaluate that library when browser interaction is the main task and you can manage the surrounding crawl workflow yourself. This recommendation concerns scope; no comparative run here establishes lower disk use or faster execution.
Scrapy is a Python framework for extracting structured website data. Its README makes it a relevant candidate when extraction and downstream processing belong in Python. We did not run a comparison between these projects.
What the documentation score covers
Documentation scores 4/5 on an editorial scale: 1 means no usable orientation, 2 means basic orientation with major gaps, 3 means useful setup and feature explanations with material gaps, 4 means clear setup, storage and integration explanations within the reviewed extract, and 5 requires independently verified coverage of the documented paths. The supplied README supports 4 through its installation instructions, storage default and browser-integration example. This is a judgment about that extract, not an audit of the full documentation site or proof that its examples work in our sandbox.
Setup ease, community support and production maturity remain unassessed. The successful installation and build are recorded findings, but the evidence does not establish consumer setup ease, support quality or recurring workload reliability.
Before adopting Crawlee, pin the intended version and run a bounded crawl that exercises your chosen crawler and storage path. Inspect saved records, failed requests and browser startup where applicable.