mrkeyoor.com_
Mon 09 Nov 05:50 UTC
Dataevaluationupdated 04 Oct 2026

scrapy review

Scrapy is a Python framework for crawling websites and turning responses into structured data. It handles request scheduling, extraction, retries, throttling, exports, and processing pipelines, so you can run a sustained crawl without assembling those parts yourself.

+93stars / 7d
Verdict

Our Scrapy run passed 2,673 tests but finished with 7 failures and 76 collection/setup errors after 432 seconds, so the framework is proven in scope but this checkout did not clear a fresh-container suite. Use it for a crawl that needs scheduling, throttling, exports, and recovery rather than a few isolated requests. Teams embedding it into an existing async application should budget time for the reactor model and verify their own test path first.

We ran it

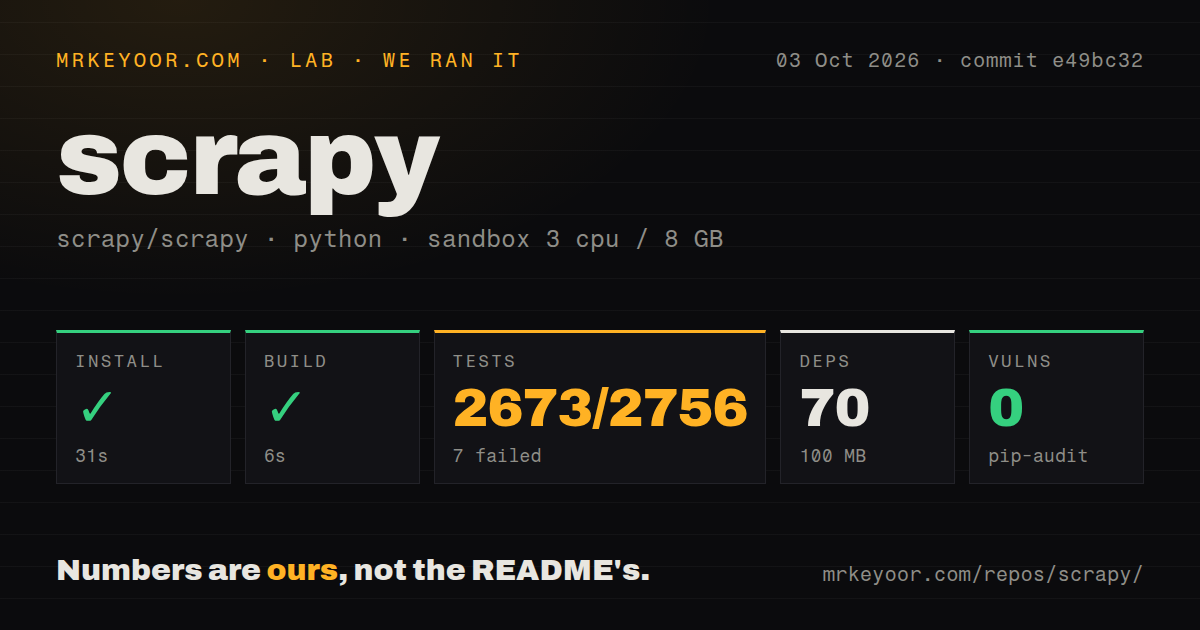
Lab card: what happened when we ran scrapyScreenshot of scrapy (scrapy.org)
Install✓ · 31s70 packages · 100 MB
Build✓ · 6s
Tests✗ · 432s2673 passed · 7 failed · 50 skipped · 76 errors of 2756 (pytest)
Known vulns0(pip-audit)
Repo710 files~96,670 lines of source · 5.6 MB · 7 CI workflows · tests dir

Answers from our run

Does scrapy build from source?

Dependencies installed in 31 seconds (70 packages), and the build succeeded in 6 seconds. We cloned commit e49bc32 into a clean Debian container with 3 CPUs and no project-specific setup.

Do scrapy's tests pass?

No. The project's own test command finished in 432 seconds and reported 2673 passed, 7 failed, 50 skipped, 76 collection errors (pytest).

Does scrapy have known vulnerabilities in its dependencies?

pip-audit found none in the dependency tree at the time of our run.

Who should not use scrapy?

Python 3.10 or older environments: the current README requires Python 3.11 or newer.

What are the alternatives to scrapy?

Crawlee for Python, Playwright for Python, Colly. Our Scrapy run passed 2,673 tests but finished with 7 failures and 76 collection/setup errors after 432 seconds, so the framework is proven in scope but this checkout did not clear a fresh-container suite.

Setup3/531-second install, but native packages and reactor details matter
Docs5/5Detailed guides cover crawling, deployment, asyncio, and edge cases
Community5/564,571 stars, an October 3 push, and current issue activity
Maturity4/5Broad production features, though our full suite did not pass

Discussed on

  1. hnScrapy Tips from the Pros269 points
  2. hnPython 3 comes to Scrapy249 points
  3. hnHow to Crawl the Web Politely with Scrapy139 points
  4. hnSpiderKeeper: Admin UI for scrapy/open source scrapinghub107 points
  5. hnCrawl a website with scrapy and store extracted results with MongoDB93 points

Who it’s for

Python teams building crawlers that must follow links, recover from request failures, and export structured records.
Data engineers who need concurrency controls, caching, cookies, authentication, and item pipelines in one framework.
Operators running long crawls that benefit from statistics, pause and resume support, and live inspection.
Contributors comfortable tracing asynchronous behavior across Twisted and asyncio.

Who it’s NOT for

Python 3.10 or older environments: the current README requires Python 3.11 or newer.
Browser-first scraping where the rendered DOM is the source of truth: Scrapy's docs recommend finding the underlying data request first, then using separate headless-browser tooling when that fails.
Applications that need a plain asyncio dependency with no reactor concepts: Scrapy uses Twisted, and its no-reactor mode is documented as experimental.
Teams that require a clean full suite before adoption: our commit e49bc32 run ended with 7 failures and 76 collection/setup errors.
Windows developers expecting the same pip path as Linux: the installation guide recommends conda-forge and says pip may require Microsoft C++ Build Tools.

Setup reality

Our sandbox installed commit e49bc32 in 31 seconds, adding 70 packages and using 100 MB. The build passed in 6 seconds. Pytest failed after 432 seconds: 2,673 passed, 7 failed, 50 skipped, 21 xfailed, and 76 collection/setup errors were reported out of 2,756 tests. Pip-audit found 0 known vulnerabilities.

Running a basic spider needs Python 3.11 or newer and no service credential. S3, Google Cloud Storage, images, alternate shells, HTTP/2, and other features use optional extras or their own credentials. Production targets may also need proxies, storage accounts, or browser tooling, depending on the crawl.

Scrapy depends on Twisted, lxml, cryptography, and pyOpenSSL. The docs recommend a virtual environment and list native development packages for Debian and Ubuntu. Windows pip installs may need Microsoft C++ Build Tools, while the documented easier route is conda-forge.

Scrapy earns its weight when a crawl becomes a system

A Scrapy spider can follow pagination, extract fields with CSS or XPath selectors, and yield records while the engine keeps other requests moving. That asynchronous scheduler is the reason to choose it over a loop around an HTTP client. Failed requests do not have to stop unrelated work, and settings can limit concurrency per domain, add a download delay, or let AutoThrottle adjust the pace.

The framework also owns the less glamorous parts that accumulate around a real crawler. It handles cookies, authentication, compression, caching, robots.txt, depth limits, and feed exports. JSON, CSV, and XML output can go to local storage, FTP, or S3, while item pipelines provide a place to clean or persist each record. With 96,670 lines of source across 710 files in our checkout, this is infrastructure rather than a small scraping helper.

That scope pays off when a crawl must run repeatedly and leave an auditable result. The interactive shell lets you test selectors against a response before editing a spider. Built-in statistics, pause and resume support, signals, middleware, and extensions give operators places to observe or alter behavior. A script that fetches 10 known pages probably does not need any of this. A crawler that discovers thousands of URLs often does.

Python 3.11 and the reactor model are firm boundaries

The current README requires Python 3.11 or newer. Installation can be one pip command, but the guide points out that lxml, cryptography, and pyOpenSSL may need native libraries. On Debian and Ubuntu it lists development headers for XML, XSLT, zlib, FFI, and SSL. Windows users are steered toward conda-forge because a pip installation may require Microsoft C++ Build Tools.

Scrapy still rests on Twisted even though new projects enable asyncio by default. Its documentation warns that importing twisted.internet.reactor can install a reactor as a side effect, after which the process cannot switch to a different one. There are helpers for crossing between Deferred objects and asyncio futures, but an application with an established event-loop policy needs deliberate integration. The reactorless path introduced in Scrapy 2.15 remains labeled experimental.

Scrapy 2.19.0 added an experimental aiohttp download handler that becomes the default without a reactor. The same release added RemoteControl, which lets a separate official MCP server inspect and control a running crawl over HTTP. That can expose crawl statistics, scheduler state, settings, and even runtime changes. It is useful for diagnosis, but enabling control over a live crawl also deserves the same access review as any other operational endpoint.

What happened when we ran it

Our sandbox installed commit e49bc32 in 31 seconds. It pulled 70 packages and occupied 100 MB on disk, then completed the build in 6 seconds. The unprivileged Debian container had 3 CPUs, 8 GB of RAM, Python 3.12, and no secrets. Pip-audit reported 0 known vulnerabilities. The repository included 7 CI workflow files and a tests directory, but no Dockerfile.

Pytest did not finish cleanly. After 432 seconds, it reported 2,673 passed, 7 failed, 50 skipped, 21 xfailed, and 76 collection/setup errors out of 2,756 tests. All 7 named failures were in tests/test_mail.py. Their shared error said is_reactorless() was called without an installed reactor or a running asyncio loop.

The log tail also showed unknown pytest.mark.asyncio warnings while collecting tests/test_utils_signal.py and tests/test_zz_resources.py. It does not establish why the marker was unknown, nor does it explain every setup error. We cannot turn that output into a dependency diagnosis. The useful finding is narrower: most tests passed, but commit e49bc32 did not give us a green full suite in the supplied fresh container.

JavaScript-rendered pages need another layer

Scrapy downloads responses; it does not pretend every response is the browser's final DOM. Its dynamic-content guide first recommends finding the underlying JSON or other data request in browser developer tools, then reproducing it directly. That is often the cleaner and cheaper crawl. When the content exists only after browser execution, the docs point to separate headless-browser options.

This boundary should shape the tool choice. Playwright is a better starting point when every target requires clicking, waiting on client-side state, or reading rendered layout. Crawlee for Python puts HTTP and Playwright crawlers in one library. Scrapy remains the stronger fit when request scheduling, extraction pipelines, throttling, and recoverable long runs are the center of the job.

October activity supports the maturity claim

GitHub showed 64,571 stars and 313 open issues and pull requests, and the repository was pushed on October 3, 2026. The latest release, 2.19.0, shipped on September 10. Recently updated work included engine refactoring, IPv6 proxy support, WebSocket support, and a report about resumed jobs overwriting batched feed files. The queue is large, but current pushes and discussion show maintainers are working in it.

Scrapy is the sensible default for a Python team whose scraper has grown into an operating service. Its docs tell you where the sharp edges are, and the 31-second installation was straightforward on our box. The failed suite changes the contribution decision: reproduce those reactor and collection errors in your environment before treating a local source checkout as release-ready.

Alternatives

ProjectWhat it isPick it when
Crawlee for PythonA Python crawling library with HTTP and Playwright-based crawler options.pick this instead when browser automation and proxy rotation should be first-class parts of the same Python toolkit.
Playwright for PythonPython bindings for controlling Chromium, Firefox, and WebKit.pick this instead when interaction with a rendered page matters more than crawl scheduling and item pipelines.
CollyA Go framework for writing crawlers and scrapers.pick this instead when your team wants a Go-native crawler and does not need Scrapy's Python ecosystem.

Sources

  1. Scrapy README
  2. Scrapy installation guide
  3. Scrapy asyncio guide
  4. Scrapy dynamic content guide
  5. Scrapy 2.19.0 release
  6. Scrapy GitHub repository

More data reviews

rerun · telegraf · rocksdb · redash · akshare · DB-GPT · the whole board →