
Should you adopt it?
Open Deep Research is archived and read-only. GitHub's notice on issue 283 dates the archival to August 21, 2026. Adopt it when you want this research-agent design and can maintain a fork. For a new service, first establish that its workflow, failure handling and operating requirements fit your application.
The README at our tested commit separates summarization, research, compression and final report writing into configurable model roles. Tavily is the default search API; the documentation also describes native OpenAI and Anthropic search and MCP configuration. These are documented capabilities, not combinations we validated in our sandbox.
What our sandbox established
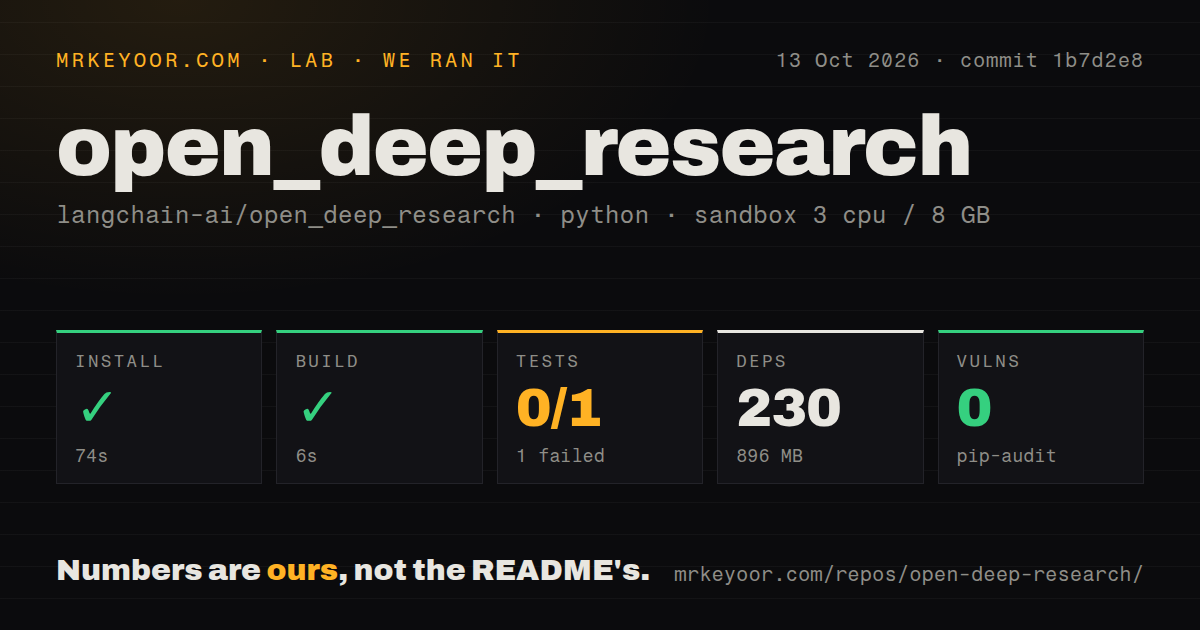
Our run on October 13, 2026 tested commit 1b7d2e8 in our sandbox. Installation succeeded in 74 seconds, and the recorded build step succeeded in 6 seconds. The installed environment contained 230 packages occupying 896 MB.
Our harness records each command step's outcome, exit code and elapsed wall-clock time, alongside parsed test counts and retained log tails. The test command returned exit code 1 after 20 seconds. Its stored parser summary records 0 passed, 1 failed, 0 skipped and 0 errors. That summary does not establish exhaustive unique test coverage; we performed no new execution or complete-log reconciliation for this correction.
The raw failure names src/legacy/tests/test_report_quality.py::test_response_criteria_evaluation. LangSmith rejected the request to /datasets with HTTP 401 and an Invalid token response. This establishes an authentication blocker in that test path. It does not show whether a correctly authenticated run would satisfy the report-quality assertion.
The raw pytest footer separately reports 1 failed and 11 warnings in 10.74 seconds. That is pytest's reported duration; the attached harness records 20 seconds for the command step. The warnings span src/legacy/graph.py, src/legacy/utils.py and src/legacy/multi_agent.py. They include deprecated LangGraph imports and schema arguments, plus a warning about langchain-community maintenance. The warnings are separate from the authentication failure.
The audit record contains 0 reported pip-audit advisories. Scan coverage is unknown: the supplied record does not establish how many packages were scanned. This result is not a security assessment.
The successful build step does not establish that Studio started, a research workload completed or a deployment worked. We did not measure report accuracy, research latency, model costs or failure recovery. The testing-methodology page explains the publisher's approach and limitations; its current text does not establish which methodology version governed this older run.
Check child failures before trusting completion
Issue 283 reports that a child ConductResearch exception can end the research phase normally and allow final report generation to continue with empty or partial findings. Its reproduction identifies a different commit, 1f24f1142db24f81e29eb88751985a00ec8ed580, so it is a reported failure path to investigate, not a result reproduced by our run at 1b7d2e8.
Before deploying a fork, test what happens when one research branch fails while another succeeds. Require the application to expose the failure and make the status of partial findings clear. Our authentication-blocked legacy test provides no evidence that the main graph handles that case correctly.
Setup and evaluation are separate decisions
The pinned README starts with an environment file and a local LangGraph development server. Its default model roles use OpenAI models, and its default search route uses Tavily. Model selection must account for structured output and tool calling; a provider name alone is not a compatibility test.
The README describes Deep Research Bench evaluation through LangSmith and warns that running its 100 examples can cost approximately $20 to $100 depending on model selection. That is the project's estimate, not our measured cost. Its published benchmark results belong to their named configurations and commits; we did not reproduce them, and the supplied leaderboard fetch was inaccessible.
A useful next step is a single authenticated research request whose sources you can check, followed by a deliberate child-failure test. Save the configuration and output before committing to a larger evaluation or deployment.
Which alternatives fit a different requirement?
GPT Researcher documents research reports using web and local documents. Consider it as a replacement candidate when those source types and its documented frontend or export options matter. Its README establishes those capabilities, not superior accuracy or reliability in our environment.
Local Deep Researcher documents local LLM use through Ollama or LMStudio. Consider it as a replacement candidate when local model hosting is the priority. It still performs web search, so local inference does not mean offline research.
PaperQA2 focuses on retrieval augmented generation over documents, with an emphasis on scientific literature. Choose it for questions grounded in a document collection. It can also complement an open-web workflow by handling a separate literature corpus; it is not evidence of a drop-in replacement for this agent.
How to read the scores
These are editorial ratings, not measured product performance. The scale is 1 for severe obstacles, 2 for substantial constraints, 3 for workable provision with gaps, 4 for broad documented provision and 5 for broad provision corroborated by successful validation. Each dimension uses its own evidence: setup considers the recorded installation and prerequisites; docs considers the supplied documentation; community considers upstream support availability; maturity considers validation and operational limitations. Stars do not establish support quality, and a documentation score does not certify runtime behavior.