What Litho produces, and what our run establishes
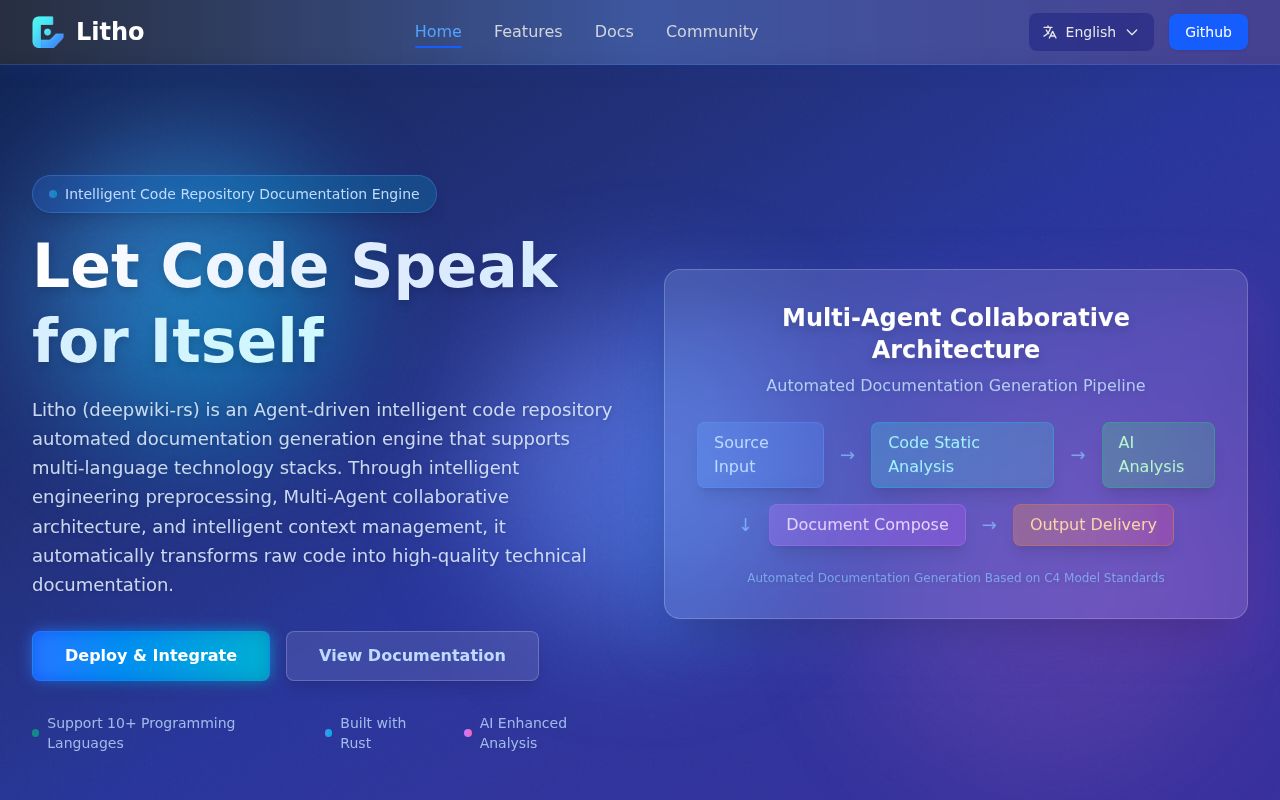
Litho (deepwiki-rs) aims to turn source code into an architecture draft. Its README describes C4 diagrams, project and workflow overviews, module notes, boundary documentation and database documentation for SQL projects. That makes it a candidate for developers mapping an unfamiliar service, provided someone can check the generated account against the system.
The README describes four stages: preprocessing, research, documentation generation, and verification. Its research stage infers architectural roles from code structure and naming. The documented verification stage checks diagram syntax and documentation coverage. Those checks do not establish that an inferred responsibility or relationship matches runtime behavior.
The README also promotes accuracy, automatic synchronization and time savings. Our recorded run did not measure those claims.
Our recorded run: successful commands, an unresolved test count
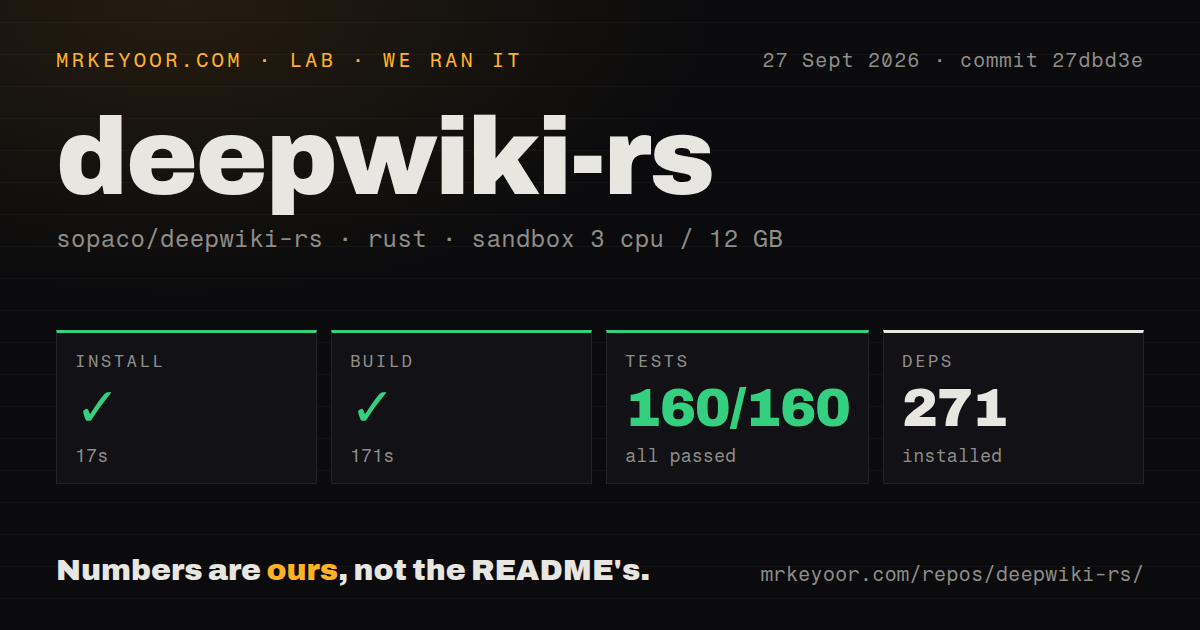
On September 27, 2026, our recorded run used commit 27dbd3ed74535213e7c40be8abcdcec4145bebf2. The dependency-download step completed in 16.680 seconds, the build step in 170.614 seconds, and cargo test in 37.463 seconds. The stored summary rounds these to 17, 171 and 37 seconds and records a dependency count of 271.
The download log is evidence of downloaded dependencies. It is not an installed-binary check. The build log identifies deepwiki-rs v1.6.0 and a successful development-profile build; it does not document a release-profile installation or execution of the installed CLI.
The test command exited successfully. However, the raw tail repeats the same Cargo summary around a replay marker. The legacy parser stored 160 passed, 0 failed and 160 total, but unique and exhaustive counts have not been verified. We therefore do not present 160 as the number of distinct passing tests, or substitute the visible summary's count as a verified project total.
The environment record lists 3 CPUs, 12 GB of memory and image label lab-rust:1. The repository scan measured 209 files, approximately 25,532 source lines and 3 MB, with 1 CI workflow, no Dockerfile and no tests directory. Tests appear inside Rust modules in the raw output, so the directory observation does not mean tests are absent.
No installed-binary check, model-backed documentation generation, output review, cost benchmark or audit result is recorded. The run supports a narrow buildability finding at this commit.
Setup still includes model configuration
The README documents Rust 1.70 or later and Cargo as prerequisites. That is the project's stated minimum, not a compatibility result from our run. It also shows model endpoint, API key, efficient-model and powerful-model options, plus a litho.toml example for external knowledge.
The advanced examples deserve checking before use. One spells a model option --model-poweruful; the same example uses --llm_api_key, while another README example uses --llm-api-key, and repeats the efficient-model option. These are visible inconsistencies in the documentation. The supplied extracts do not include the CLI definition, so they do not establish every accepted spelling. After obtaining a working binary, inspect deepwiki-rs --help before adapting those examples. We did not execute that check.
Version 1.6.0's release notes document stage-skipping flags, cache clearing, verbose logging and chunking validation. Those controls may help structure a pilot, but the release notes do not establish end-to-end generation reliability for a particular repository.
Historical reports explain why a pilot matters
In issue 107, opened June 9, 2026, a user reported spending more than $100 in tokens. Their log says preprocessing analyzed 1,697 files; a later research-agent model request ended with HTTP 504 after eight attempts. Those were model-request attempts in another user's run, not failed tests in our sandbox. The issue was closed on August 14, 2026 with a maintainer response pointing to Terrain. Closure does not demonstrate that the workload succeeds in Litho v1.6.0.
In issue 87, opened February 19, 2026, another user reported an approximately 400 MB internal repository, 11,095 identified source files and memory peaking at 127.38 GB before allocation failed. It was closed on May 16, 2026 after the maintainer suggested a skill-based approach. This is a historical user report, not our memory benchmark or a measured current limit.
Both reports predate version 1.6.0. Use them as reasons to measure your own bounded workload, rather than as predictions of its cost or memory demand.
External context helps frame the draft
The README documents external knowledge inputs in PDF, Markdown, SQL, YAML, JSON and plain text. Its configuration example routes architecture documents and database schemas to selected agents. Supplying an existing architecture decision can give the generator context that source structure alone does not explain; our run did not test whether the resulting documentation uses that context correctly.
Source traceability needs a separate acceptance check. In issue 71, the maintainer said on November 26, 2025 that source-code referencing was not supported. The issue was later closed with a Terrain announcement. The supplied current README describes cross-referencing but does not establish sentence-level source citations. Verify that requirement directly before relying on Litho for an audit workflow.
The current README says Litho has evolved into Terrain while Litho remains a focused C4 documentation generator. It separately describes Litho Book as a reader for generated Markdown, with search and AI question answering. This review concerns sopaco/deepwiki-rs; our recorded build does not evaluate those other products.
Choose the output you need
DeepWiki Open's supplied README describes an interactive repository wiki with diagrams and guided code tours. Consider it when navigation through generated repository documentation is the priority. The extract does not substantiate the earlier Q&A comparison.
Doxygen documents extraction from source files into an HTML documentation browser or offline reference manual. Consider it when that reference-documentation workflow fits the task. We did not run either alternative or compare output quality.
How to read the ratings
These are editorial evidence ratings, not benchmark results. The scale is 1 for insufficient evidence to recommend a broad trial, 2 for limited support with major unanswered questions, 3 for a documented approach with a bounded successful check, 4 for repeated relevant workload evidence, and 5 for broad independent validation. Missing evidence lowers confidence; it does not prove a defect.
Setup receives 3/5 because dependency download and a development build completed, while binary installation and model configuration remain unverified. Documentation receives 3/5 because the README explains the workflow and knowledge configuration but contains inconsistent advanced examples. Community receives 2/5 because the supplied issues show maintainer responses but do not establish adoption or dependable support. Maturity receives 2/5 because release notes and successful local commands do not resolve generation accuracy, large-workload behavior or the test-count ambiguity.
For a useful next step, select one service whose architecture a maintainer already understands. Record the commit, model configuration, spending and peak memory, then check generated responsibilities and relationships against source and deployment configuration before widening the scope.