Seven platforms share one browser-backed workflow
MediaCrawler collects public posts, creator pages, and comments from Xiaohongshu, Douyin, Kuaishou, Bilibili, Weibo, Tieba, and Zhihu. Instead of reimplementing each site's signing scheme, it keeps a logged-in browser context and evaluates JavaScript there to obtain request parameters. That is a practical choice for personal research because the browser already holds the login state. It also means the crawler inherits every platform change that affects pages, cookies, signatures, or account checks.
The output side is unusually flexible for a research repo. Records can go to CSV, JSON, JSONL, Excel, SQLite, or MySQL. Media downloads cover 5 of the 7 listed platforms, with Bilibili using ffmpeg for its highest-quality DASH path and falling back to a direct MP4 route when ffmpeg is missing. Comment collection is disabled by default, so a first successful crawl does not mean every advertised data type was collected.
What happened when we ran it
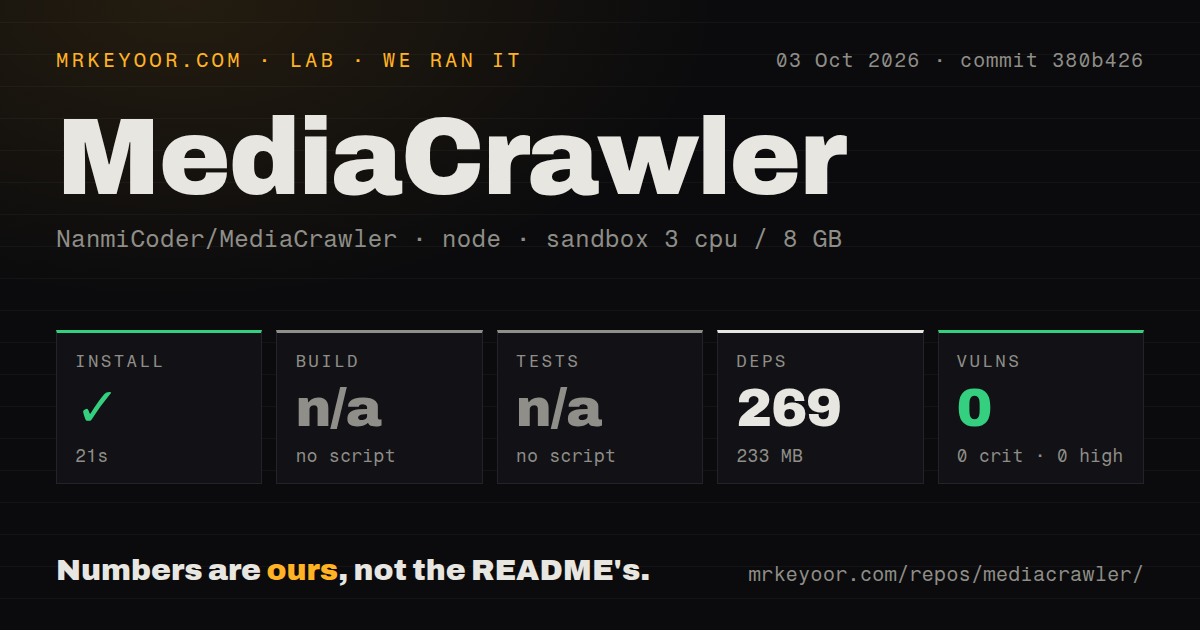
Our sandbox installed commit 380b426's npm dependencies in 21 seconds. It pulled 269 packages and occupied 233 MB on a fresh Debian container with 3 CPUs, 8 GB of RAM, Node 22, no secrets, and no elevated privileges. Npm audit reported 0 known vulnerabilities: 0 critical, high, moderate, or low.
The root package.json did not define a generic build script or test script, so the harness skipped both steps. This matters because MediaCrawler is primarily a Python application, while the npm package at the repository root contains VitePress documentation commands. Our run therefore proved that the Node documentation dependency install worked. It did not prove that the Python crawler starts, that a browser can log in, or that any of the 7 platform connectors return data.
The checkout itself contained 347 files, about 37,189 lines of source, and used 25.8 MB. We found 1 CI workflow, no Dockerfile, and a tests directory. Since the selected npm path had no test target, none of those Python tests ran in our sandbox. Treat the absent test result as an unmeasured part of this review, not as a passing suite.
Chrome 144 and a live login keep an operator in the loop
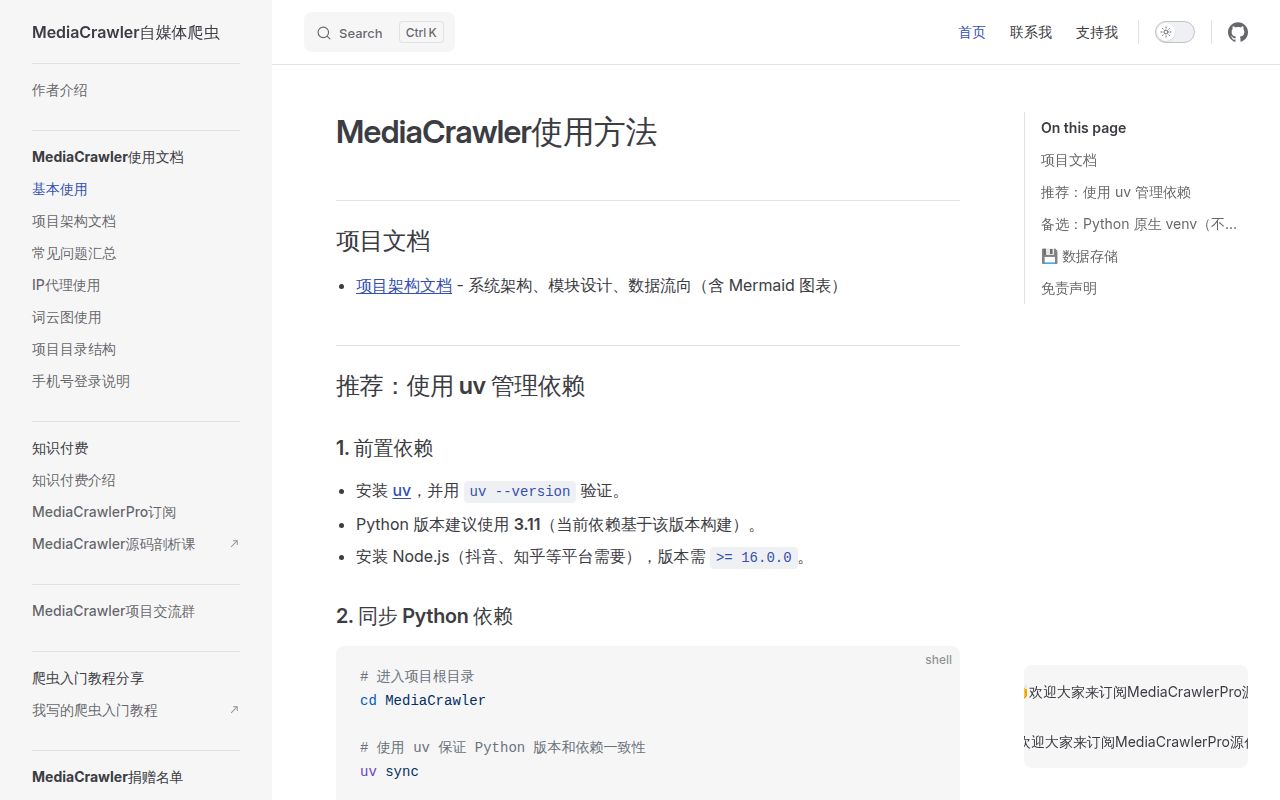
The current Chinese README recommends Python 3.11 or newer with uv, plus Node.js 16 or newer. Its default route connects to an existing Chrome 144 or newer instance through the Chrome DevTools Protocol on port 9222. You enable remote debugging, start the crawl, accept Chrome's confirmation dialog within 60 seconds, and complete the platform login. Standard Playwright mode is available, but then you must install its browser driver.
That flow is friendlier to account state than starting with an empty browser profile, yet it is awkward on a remote worker. Cookies become operational secrets. A blocked account or changed confirmation flow can stop a scheduled job before collection begins. There is no Dockerfile to encode Chrome, Python, uv, Node, and optional ffmpeg into one maintained image, so anyone turning this into a repeatable service has to build that packaging.
The English guide exists, but the Chinese guide is the source to trust
English documentation covers the supported platforms, commands, WebUI, output formats, and login idea. It is useful enough to understand the project. Several details no longer match the Chinese README or current pyproject, though: the English native-venv section mentions Python 3.9.6, while pyproject requires Python 3.11 or newer, and its Playwright instructions do not reflect the newer default CDP wording.
The WebUI adds another two-process setup during development: a FastAPI service on port 8080 and a Vite server on port 5173. Production assets can be built into the API package, but our measured root npm path had no generic build target and did not exercise that webui subdirectory. English-only teams should compare both READMEs before turning any command into automation.
The non-commercial license rules out a business deployment
The repository's custom Non-Commercial Learning License 1.1 permits use, copying, modification, and merging for non-commercial learning. It prohibits commercial use without written consent and also bars large-scale crawling or activity that disrupts a platform. Those are product constraints, not a minor legal footnote. A company evaluating MediaCrawler for customer research, lead generation, or a paid dataset needs permission before architecture work begins.
Even permitted research requires care with platform terms, personal data, and account controls. The README tells users to follow applicable law and avoid infringement. MediaCrawler provides collection code; it does not grant a right to collect a target site's data. The narrow license also explains why Crawlee or Scrapling may be a better base when you need to own the policy and connector work in a commercial setting.
An October 3 push is active, but 164 issues remain open
GitHub recorded 66,151 stars and a last push on October 3, 2026. Separate issue searches showed 164 open issues and 48 open pull requests, which together match the repository API's 212 combined count. That is current development with a large review and support queue. The project has no published GitHub release, so adopters must pin a commit instead of choosing a tagged release with notes.
Recent reports show why pinning and per-platform checks matter. Issue 985 documents a Xiaohongshu creator crawl that logged in successfully, connected to Chrome, and then stopped on a JSON parsing error. Issue 725 reports that a Windows CDP session can leave the browser open after a crawl. For non-commercial research, MediaCrawler saves substantial connector work. For a dependable service, the license and browser-operated runtime end the evaluation before its star count should sway you.