Thirty-five files separate technical claims from social leads
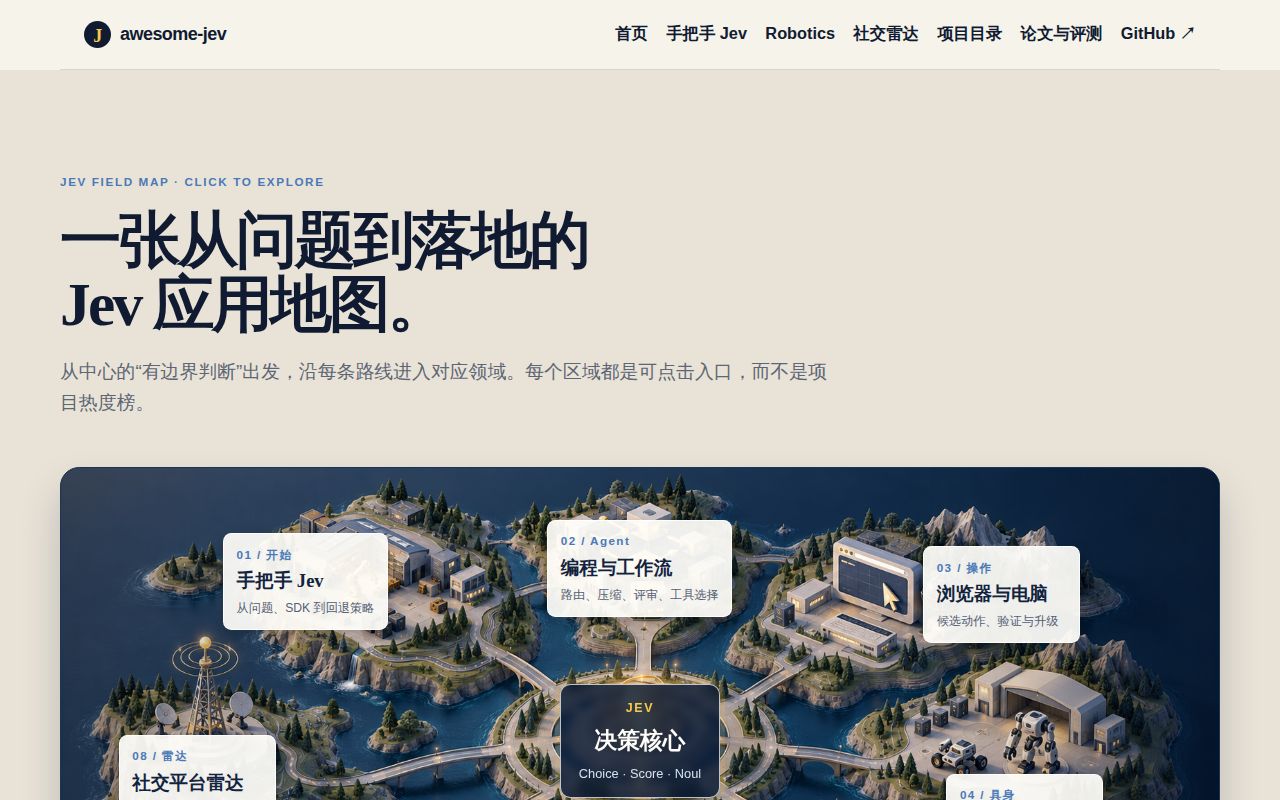
Awesome Jev contains 35 files at commit 71f52de, including 14 Markdown documents and 11 static HTML pages. The default README is Simplified Chinese. README_EN.md provides a full English edition, and the catalog, research, installation, hands-on, robotics, and source-audit guides have English counterparts. The Pages site adds search and browsing without replacing the reviewable Markdown source.
The source audit is the reason to use this list instead of searching Jev on GitHub. One recorded pass checked metadata for 51 repositories and stopped when anonymous API limits arrived rather than filling gaps with old counts. X and Xiaohongshu posts can supply leads, but restricted pages remain labeled as unreadable. Project features are checked against repositories, papers, documentation, or author material before moving into the main catalog.
Jev 1.13.0 is presented as a dated product snapshot
The English guide records Jev 1.13.0, its Choice, Score, and Noul primitives, direct API limits, gateway routes, pricing, and the distinction between a probability distribution and task accuracy. It places the model inside an agent loop as a bounded decision layer. Permission checks, tool execution, fallbacks, and sandboxing remain application responsibilities. That is a useful correction to projects that present a model judgment as a security boundary.
Every volatile figure carries a date or source. The model alias and rate limits came from TypeSafe's documentation; gateway schemas came from their respective providers. The guide warns that native TypeSafe, Vercel, Cloudflare, OpenRouter, and framework adapters do not become semantically identical because they expose similar primitives. Since the full audit dates to September 24, production code should reopen the linked provider documentation before using any recorded identifier or limit.
Research coverage keeps failures beside headline results
The v0.1.0 research section starts with 13 early papers and adds later security, medical, legal, mobile, gaming, and evaluation work. Results stay attributed to their authors. A reported 100% judge result is tied back to 5 fixed traces, while a Chinese ticket study keeps its 40-item sample visible. Another comparison notes that type-correct output can still fail after option names and definitions are swapped.
This editorial habit makes the collection useful for deciding what to test. The catalog does not merge unlike benchmarks into a ranking, and it distinguishes a source repository from an independently reproduced result. Open alternatives, hosted integrations, agent gates, browser projects, robotics demos, and papers sit in separate sections. A reader can find a project quickly, then follow the source log to see whether the evidence is code, an author measurement, a design claim, or an inaccessible social post.
What happened when we ran it
We did not run commit 71f52de in our sandbox. The lab found no supported software ecosystem and no Dockerfile, so it had no truthful install, build, or test command to execute. The repository is a publication: Markdown, 11 HTML files, CSS, JavaScript, images, and one GitHub Pages workflow. There are no model weights or inference service behind the map.
Our measurement setup was a fresh Debian container with 3 CPUs and 8 GB of RAM, but those resources were irrelevant because nothing executable matched the lab harness. The Pages workflow checks out the repository, uploads docs/, and deploys it. It does not crawl links or rerun the studies in the catalog. A green deployment would show that files were published, not that prices, stars, papers, or third-party claims remain current.
One deployment workflow leaves verification to editors
The repository's 1 file under .github/workflows/ only deploys changes under docs/. It performs no automatic comparison between Chinese and English pages, no external-link check, and no metadata refresh. The contribution rules ask humans to attach authors, dates, original links, sample sizes, versions, and measurement conditions. That process is thoughtful, but it remains a manual editorial control.
Manual curation is defensible for a fast-moving field if readers respect the timestamps. The README marks its full-audit baseline as September 24 and its incremental review through September 28. commit 71f52de then merged WaterSheep on October 4, after the badge date. That update shows the list is still maintained, while also showing why a single verification date cannot describe every entry.
Version 0.1.0 is active but only weeks old
Promethe-us created the repository on September 20, published v0.1.0 on September 27, and pushed commit 71f52de on October 4. GitHub showed 137 stars, 8 forks, and 0 open issues or pull requests on October 8. Its history includes 12 closed pull requests and 1 closed issue, with additions and documentation changes often handled within a day.
A clean queue does not establish long-term coverage. Jev launched days before the repository, and its ecosystem, gateways, pricing, papers, and open alternatives were changing through the audit window. Awesome Jev earns a bookmark because it records where each claim came from and admits what it could not verify. The useful habit is to start there, then open the primary source whose date controls your decision.